西维蜀黍

【macOS】brew 使用

Homebrew

Homebrew是一个包管理器,用于安装Apple没有预装但你需要的UNIX工具。(比如著名的wget)。

Homebrew会将软件包安装到独立目录(/usr/local/Cellar),并将其文件软链接至/usr/local。

Installation

安装Homebrew。将以下命令粘贴至终端

/usr/bin/ruby -e "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/master/install)"

脚本会在执行前暂停,并说明将它将做什么。

  ...


【Docker】Container 常用命令

Docker 启动

Docker 是服务器—-客户端架构。命令行运行docker命令的时候,需要本机有 Docker 服务。如果这项服务没有启动,可以用下面的命令启动:

# service 命令的用法
$ sudo service docker start

# systemctl 命令的用法
$ sudo systemctl start docker
  ...


【Redis】Codis

Codis

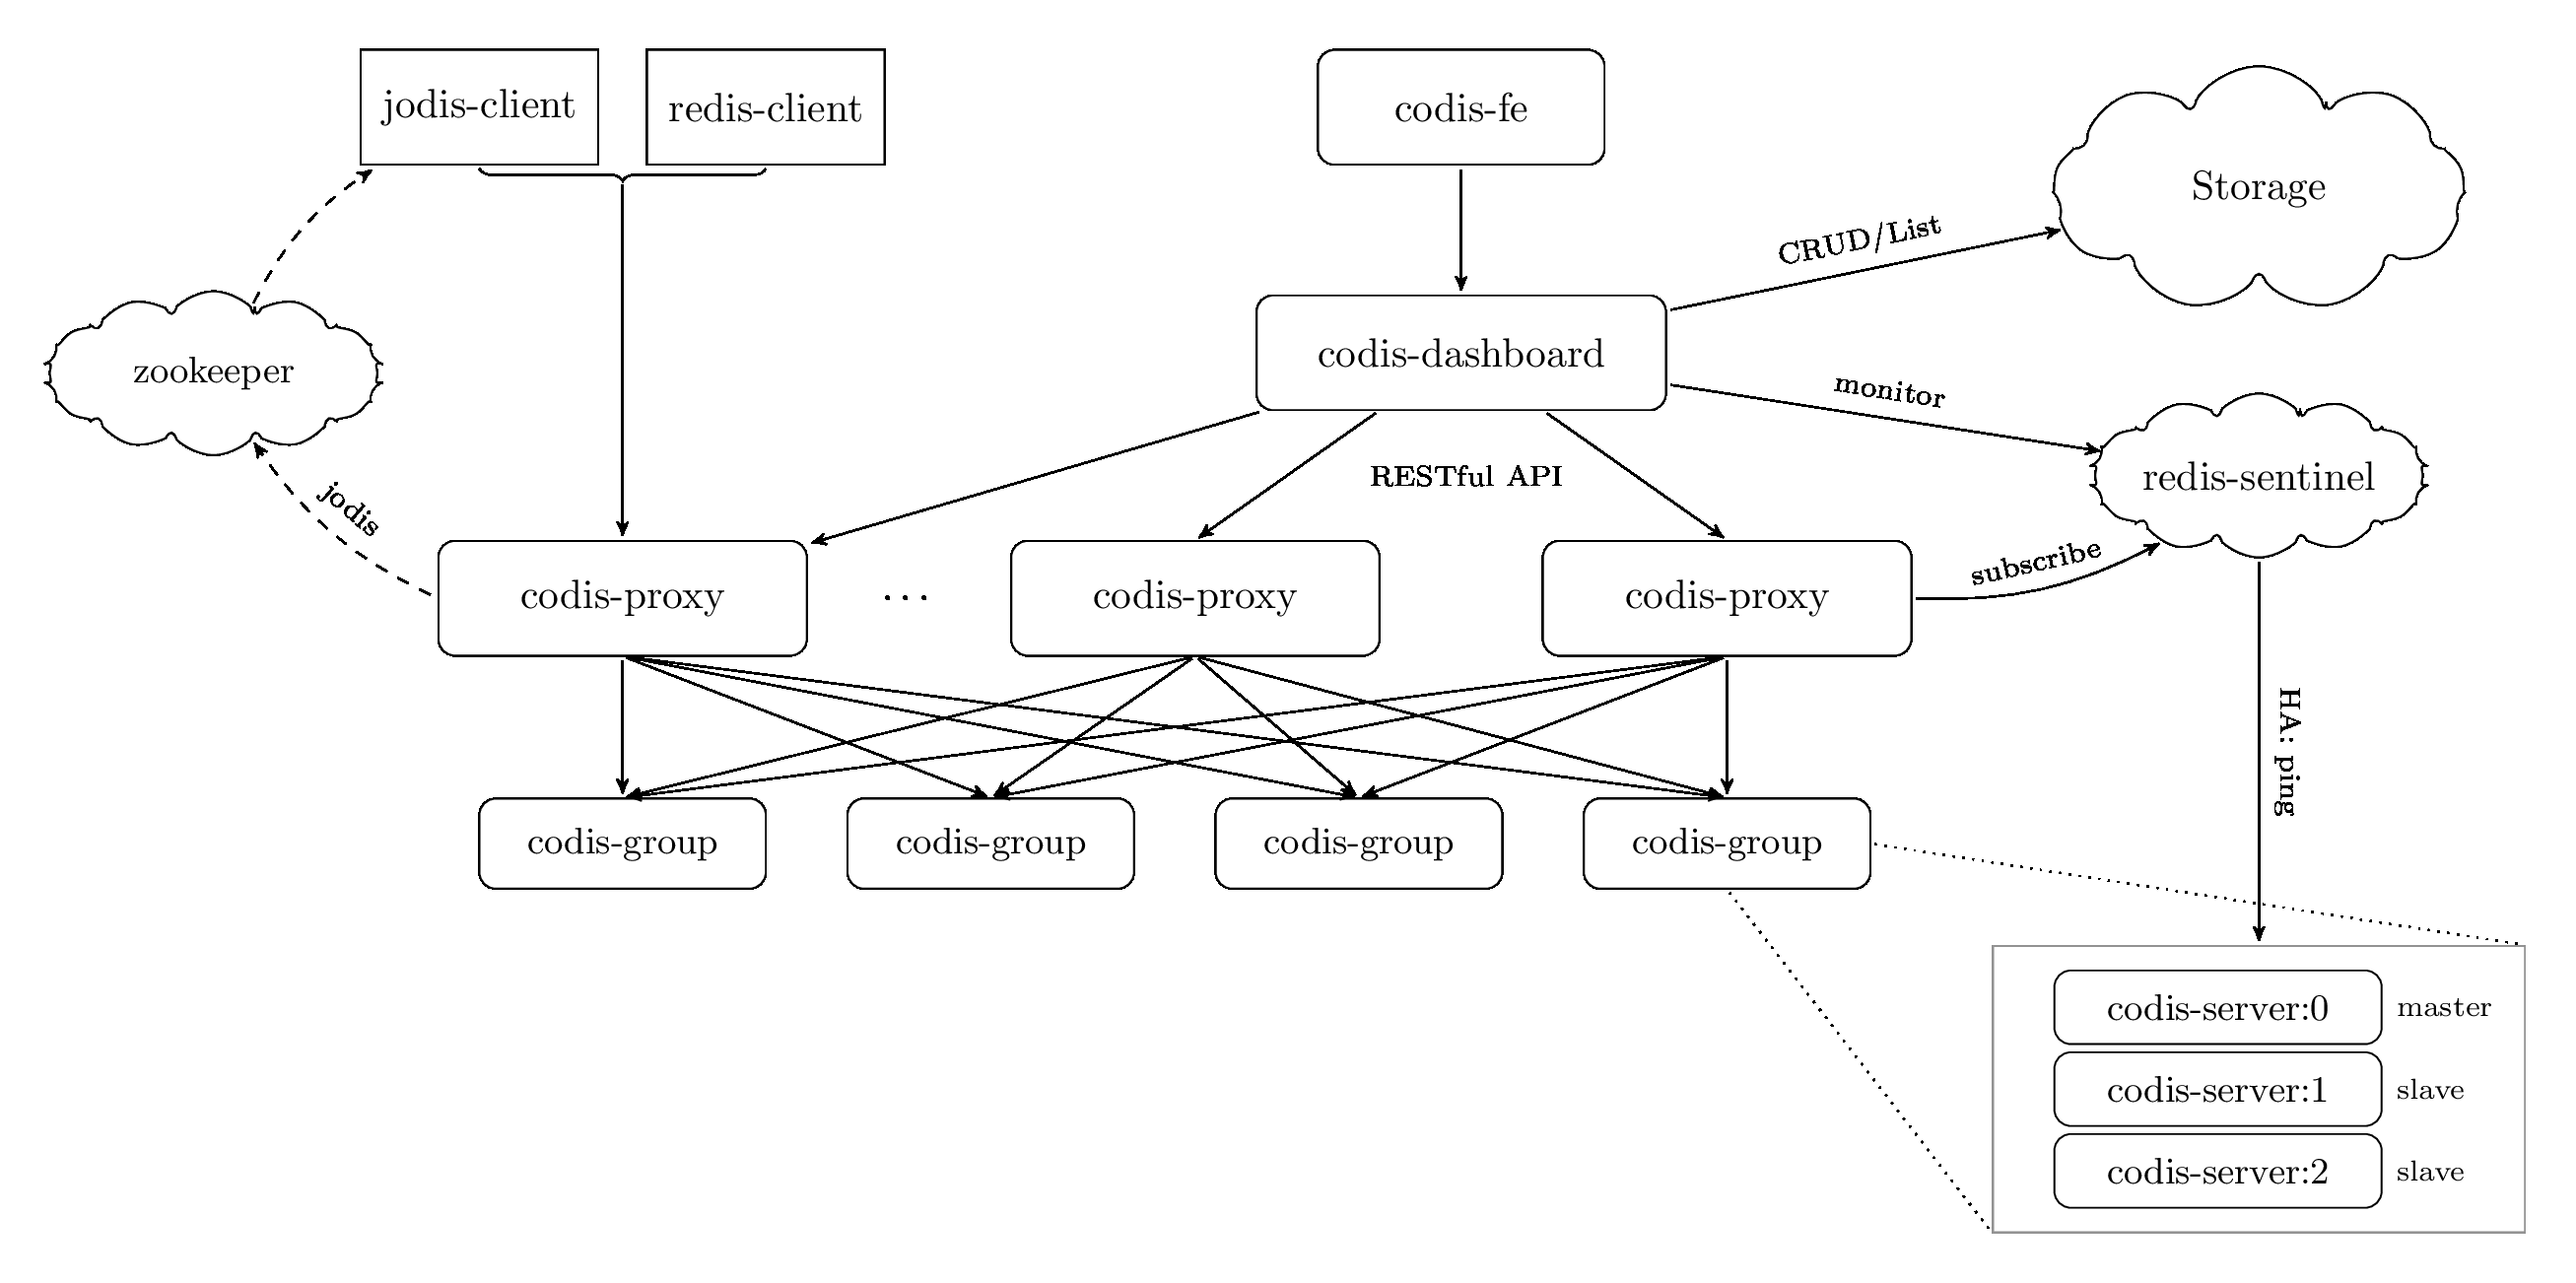
Codis 是一个分布式 Redis 解决方案, 对于上层的应用来说, 连接到 Codis Proxy 和连接原生的 Redis Server 没有显著区别 (不支持的命令列表), 上层应用可以像使用单机的 Redis 一样使用, Codis 内部(其实是Codis Proxy)会处理请求的转发(转发到Codis Server), 不停机的数据迁移等工作, 所有后边的一切事情, 对于前面的客户端来说是透明的, 可以简单的认为后边连接的是一个内存无限大的 Redis 服务。

Architecture

  ...


【Redis】Redis pipeline

Background

Redis is a TCP server using the client-server model and what is called a Request/Response protocol.

This means that usually a request is accomplished with the following steps:

  • The client sends a query to the server, and reads from the socket, usually in a blocking way, for the server response.
  • The server processes the command and sends the response back to the client.

So for instance a four commands sequence is something like this:

  • Client: INCR X
  • Server: 1
  • Client: INCR X
  • Server: 2
  • Client: INCR X
  • Server: 3
  • Client: INCR X
  • Server: 4

Clients and Servers are connected via a networking link. Such a link can be very fast (a loopback interface) or very slow (a connection established over the Internet with many hops between the two hosts). Whatever the network latency is, there is a time for the packets to travel from the client to the server, and back from the server to the client to carry the reply.

This time is called RTT (Round Trip Time). It is very easy to see how this can affect the performances when a client needs to perform many requests in a row (for instance adding many elements to the same list, or populating a database with many keys). For instance if the RTT time is 250 milliseconds (in the case of a very slow link over the Internet), even if the server is able to process 100k requests per second, we’ll be able to process at max four requests per second.

If the interface used is a loopback interface, the RTT is much shorter (for instance my host reports 0,044 milliseconds pinging 127.0.0.1), but it is still a lot if you need to perform many writes in a row.

Fortunately there is a way to improve this use case.

  ...


【Redis】Redis 性能分析 Insight

Factors impacting Redis performance

There are multiple factors having direct consequences on Redis performance. We mention them here, since they can alter the result of any benchmarks. Please note however, that a typical Redis instance running on a low end, untuned box usually provides good enough performance for most applications.

Network bandwidth and latency

Network bandwidth and latency usually have a direct impact on the performance.

It is a good practice to use the ping program to quickly check the latency between the client and server hosts is normal before launching the benchmark.

Regarding the bandwidth, it is generally useful to estimate the throughput in Gbit/s and compare it to the theoretical bandwidth of the network. For instance a benchmark setting 4 KB strings in Redis at 100000 q/s, would actually consume 3.2 Gbit/s of bandwidth and probably fit within a 10 Gbit/s link, but not a 1 Gbit/s one. In many real world scenarios, Redis throughput is limited by the network well before being limited by the CPU. To consolidate several high-throughput Redis instances on a single server, it worth considering putting a 10 Gbit/s NIC or multiple 1 Gbit/s NICs with TCP/IP bonding.

But from another pespective, if bottleneck is NIC, it means that there is no obvious bottleneck at CPU. And thus upgrade the NIC could improve the performance.

But sometimes, if we use 10Gb/s NIC, but somehow the network throughput cannot close to 10Gb/s, and the performance analysis becomes more complex.

$ redis-benchmark -h 192.168.18.128 -c 100 -r 1 -l -t set -d 4000
Summary:
  throughput summary: 79113.92 requests per second
  latency summary (msec):
          avg       min       p50       p95       p99       max
        0.736     0.256     0.743     0.791     0.863     7.535

^RT: rps=104100.0 (overall: 100567.6) avg_msec=0.568 (overall: 0.585)
^CT: rps=100318.7 (overall: 100467.0) avg_msec=0.583 (overall: 0.584)

CPU

CPU is another very important factor. Being single-threaded, Redis favors fast CPUs with large caches and not many cores. At this game, Intel CPUs are currently the winners. It is not uncommon to get only half the performance on an AMD Opteron CPU compared to similar Nehalem EP/Westmere EP/Sandy Bridge Intel CPUs with Redis. When client and server run on the same box, the CPU is the limiting factor with redis-benchmark.

RAM

  • Speed of RAM and memory bandwidth seem less critical for global performance especially for small objects. For large objects (>10 KB), it may become noticeable though. Usually, it is not really cost-effective to buy expensive fast memory modules to optimize Redis.

Misc

  • Redis runs slower on a VM compared to running without virtualization using the same hardware. If you have the chance to run Redis on a physical machine this is preferred. However this does not mean that Redis is slow in virtualized environments, the delivered performances are still very good and most of the serious performance issues you may incur in virtualized environments are due to over-provisioning, non-local disks with high latency, or old hypervisor software that have slow fork syscall implementation.
  • When the server and client benchmark programs run on the same box, both the TCP/IP loopback and unix domain sockets can be used. Depending on the platform, unix domain sockets can achieve around 50% more throughput than the TCP/IP loopback (on Linux for instance). The default behavior of redis-benchmark is to use the TCP/IP loopback.
  • The performance benefit of unix domain sockets compared to TCP/IP loopback tends to decrease when pipelining is heavily used (i.e. long pipelines).
  • When an ethernet network is used to access Redis, aggregating commands using pipelining is especially efficient when the size of the data is kept under the ethernet packet size (about 1500 bytes). Actually, processing 10 bytes, 100 bytes, or 1000 bytes queries almost result in the same throughput. See the graph below.
  • On multi CPU sockets servers, Redis performance becomes dependent on the NUMA configuration and process location. The most visible effect is that redis-benchmark results seem non-deterministic because client and server processes are distributed randomly on the cores. To get deterministic results, it is required to use process placement tools (on Linux: taskset or numactl). The most efficient combination is always to put the client and server on two different cores of the same CPU to benefit from the L3 cache. Here are some results of 4 KB SET benchmark for 3 server CPUs (AMD Istanbul, Intel Nehalem EX, and Intel Westmere) with different relative placements. Please note this benchmark is not meant to compare CPU models between themselves (CPUs exact model and frequency are therefore not disclosed).
  • With high-end configurations, the number of client connections is also an important factor. Being based on epoll/kqueue, the Redis event loop is quite scalable. Redis has already been benchmarked at more than 60000 connections, and was still able to sustain 50000 q/s in these conditions. As a rule of thumb, an instance with 30000 connections can only process half the throughput achievable with 100 connections. Here is an example showing the throughput of a Redis instance per number of connections:
  ...

【Redis】Redis 性能测试(redis-benchmark)

redis-benchmark

Redis includes the redis-benchmark utility that simulates running commands done by N clients at the same time sending M total queries (it is similar to the Apache’s ab utility). Below you’ll find the full output of a benchmark executed against a Linux box.

The following options are supported:

Usage: redis-benchmark [-h <host>] [-p <port>] [-c <clients>] [-n <requests]> [-k <boolean>]

 -h <hostname>      Server hostname (default 127.0.0.1)
 -p <port>          Server port (default 6379)
 -s <socket>        Server socket (overrides host and port)
 -a <password>      Password for Redis Auth
 -c <clients>       Number of parallel connections (default 50)
 -n <requests>      Total number of requests (default 100000)
 -d <size>          Data size of SET/GET value in bytes (default 2)
 --dbnum <db>       SELECT the specified db number (default 0)
 -k <boolean>       1=keep alive 0=reconnect (default 1)
 -r <keyspacelen>   Use random keys for SET/GET/INCR, random values for SADD
  Using this option the benchmark will expand the string __rand_int__
  inside an argument with a 12 digits number in the specified range
  from 0 to keyspacelen-1. The substitution changes every time a command
  is executed. Default tests use this to hit random keys in the
  specified range.
 -P <numreq>        Pipeline <numreq> requests. Default 1 (no pipeline).
 -q                 Quiet. Just show query/sec values
 --csv              Output in CSV format
 -l                 Loop. Run the tests forever
 -t <tests>         Only run the comma separated list of tests. The test
                    names are the same as the ones produced as output.
 -I                 Idle mode. Just open N idle connections and wait.
  ...


【Redis】Redis High-availability

Redis集群

当面对一个小型的Demo项目时,使用一台Redis服务器己经非常足够了,然而现实中的项目通常需要若干台Redis服务器的支持:

  • 从结构上,单个Redis服务器会发生单点故障,同时一台服务器需要承受所有的请求负载。这就需要为数据生成多个副本并分配在不同的服务器上:
  • 从容量上,单个Redis服务器的内存非常容易成为存储瓶颈,所以需要进行数据分片。

同时拥有多个Redis服务器后就会面临如何管理集群的问题,包括如何增加节点、故障恢复等操作。

为此,下文将依次详细介绍Redis中的数据分片(data sharding)、复制(replication)、哨兵(sentinel)和集群(cluster)的使用和原理。

  ...


【Redis】Redis 持久化(Persistence)

Background

Redis是一个内存数据库,所有的数据将保存在内存中,这与传统的MySQL、Oracle、SqlServer等关系型数据库直接把数据保存到硬盘相比,Redis的读写效率非常高。但是保存在内存中也有一个很大的缺陷,一旦断电或者宕机,内存数据库中的内容将会全部丢失。为了弥补这一缺陷,Redis提供了把内存数据持久化到硬盘文件,以及通过备份文件来恢复数据的功能,即Redis持久化机制。

  ...


【Redis】Redis 事务(Transaction)

Redis 事务(Transaction)

Redis通过 MULTI、EXEC、DISCARD、WATCH 等命令来实现事务(transaction)功能。

All the commands in a transaction are serialized and executed sequentially. It can never happen that a request issued by another client is served in the middle of the execution of a Redis transaction. This guarantees that the commands are executed as a single isolated operation.

事务提供了一种将多个命令请求打包,然后一次性、按顺序串行地(executed sequentially)执行多个命令的机制,并且在事务执行期间,服务器不会中断事务而改去执行其他客户端的命令请求,它会将事务中的所有命令都执行完毕,然后才去处理其他客户端的命令请求。

Either all of the commands or none are processed, so a Redis transaction is also atomic. The EXEC command triggers the execution of all the commands in the transaction, so if a client loses the connection to the server in the context of a transaction before calling the EXEC command none of the operations are performed, instead if the EXEC command is called, all the operations are performed.

以下是一个事务执行的过程,该事务首先以一个MULTI命令为开始,接着将多个命令放入事务当中,最后由 EXEC命令触发这个事务的执行,通过将这个事务提交(commit)给服务器。

  ...


【Redis】Redis Key长度与性能

Question

我们知道,在Redis中,get和set操作的time complexity均为O(1)。然而,当我们提供一个超长的key给Redis时,理论上,Redis需要花费更多内存来存储这个key。

因此,key的长度有没有可能影响Redis的性能呢?

Benchmark Script

在key为不同长度(包含的字符长度)时,Redis 的get和set操作的Performance(QPS)测试脚本

#!/bin/bash
echo "Test the length of key in Redis will influence performance..."

for (( c=1; c<=100000000000000; c=c*10 ))
do  
   echo "Current length: ${c}"
   redis-cli flushall
   redis-benchmark -n 1000000 -t set,get -r ${c} -q
done
  ...
